Now Your AI Writes Your Next Prompt: Inside Codex Composer Predictions and the Rise of Tab-to-Accept

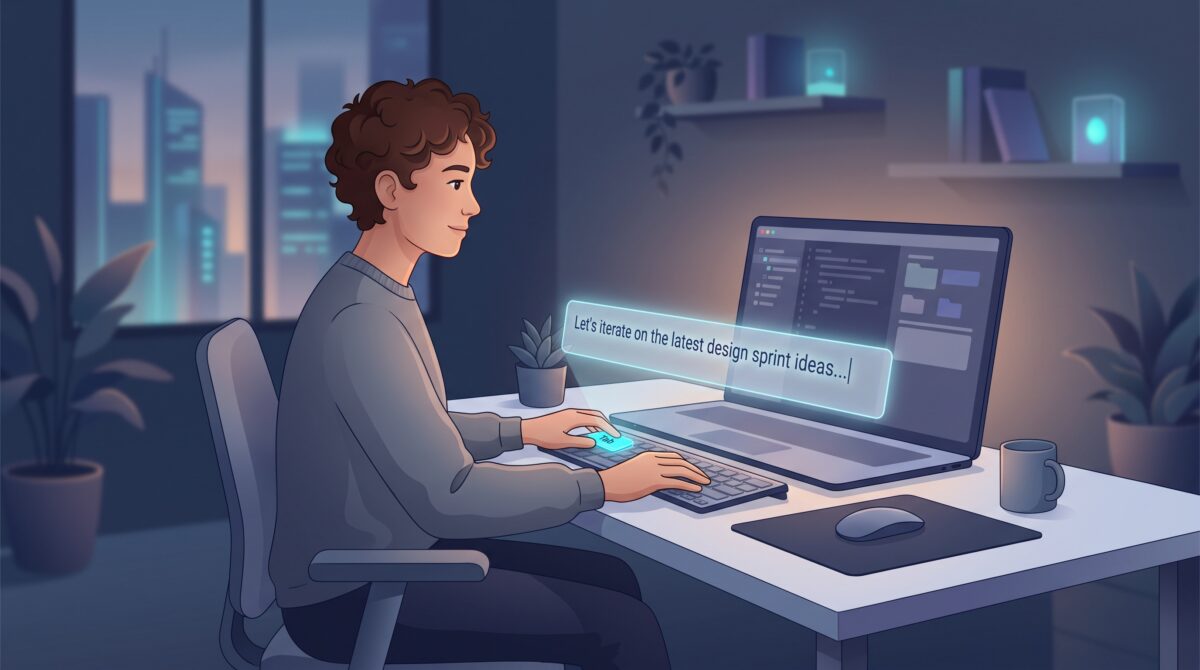
You know the small friction. The AI finishes a response, it’s good, and now it’s your move. You sit there for a second composing the obvious follow-up: “okay, now write the tests for that,” or “explain why you chose that approach,” or “apply the same change to the other file.” You type it out every time, even though a smart observer could have guessed exactly what you were about to ask.
OpenAI’s coding tool, Codex, just decided to stop making you type it. A beta feature called Composer predictions watches the conversation and, after Codex replies, quietly pre-fills a suggested next message in the box. Press Tab and it drops in as an editable draft. It’s autocomplete, but for your whole next thought instead of the next word. Here’s how it actually works, and how to use it without handing over the steering wheel.
What Composer predictions actually do
The mechanics are refreshingly simple. After Codex finishes a response, it reads your current thread and the way you tend to phrase things, then suggests a likely follow-up prompt right in the message box. You don’t open a menu or click a button; the suggestion just appears, greyed in and waiting.
Press Tab to accept it. That’s the whole gesture. OpenAI shipped this in beta in the Codex desktop app in October 2026, and it has since expanded, turning on by default for eligible Pro users and working across local and SSH threads in the latest app. During the beta, it’s included at no extra cost for those users. If you’ve ever used code autocomplete that guesses your next line, this is the same idea pushed up a level, from completing a line of code to completing your intent.
The detail that matters: accepting is not sending
Here’s the design choice that separates a helpful feature from an annoying one. When you press Tab, the predicted message lands in your composer as a draft. It does not send. You read it, change a word or ten, delete half of it, or throw it out entirely, and only then do you choose to hit send yourself.
That gap between accept and send is the entire point. It means the AI can be confidently wrong without any cost to you, because nothing happens until you say so. You get the speed of a guessed prompt with none of the risk of an action you didn’t authorize. It’s the same human-in-the-loop principle showing up across the best new agent tools, like the way agentic autofill lets an AI log in for you without ever seeing your password: the machine does the tedious part, but you stay the one who decides.
How to actually use it well
A prediction is a suggestion, not an instruction. Treat it that way and it earns its keep. A few habits make the difference:
- Read before you accept. Tab is fast, which is exactly why it’s easy to accept a prompt that’s subtly off. Glance at it first. Two seconds of reading beats sending the AI down the wrong path.
- Use it as a starting point, then sharpen. The prediction is usually in the right neighborhood but generic. Accept it, then add the specific detail only you know, the file name, the edge case, the constraint. You get the scaffolding for free and spend your effort on what matters.
- Let it break your tunnel vision. Sometimes the suggested next step is one you hadn’t considered, like “want me to add error handling here?” That’s a useful nudge. The prediction can surface the obvious-in-hindsight move you were about to skip.
When to ignore it entirely
Predictive prompting shines for the routine back-and-forth and fails for anything that needs your judgment. If you’re at a decision point, debugging something gnarly, or doing work where the how matters as much as the what, just type your own prompt. The suggestion is optimized for the likely next move, not the right one, and the likely move is wrong exactly when the stakes are highest.
The trap to avoid is letting a string of accepted predictions quietly steer the conversation. If you Tab through five suggestions in a row without really reading them, you’re no longer directing the work, you’re rubber-stamping the AI’s guess about what you’d probably say. Keeping your AI predictable and under control is a discipline in its own right, the same way you’d lock down structured outputs so a local agent doesn’t go off the rails. Use predictions to move faster on the easy parts so you have more attention for the hard ones.

Why this is showing up now
Composer predictions aren’t a one-off gimmick. They’re a sign of where the whole category is heading. As models get cheaper and faster to run, labs can afford to spend a little inference on anticipating you rather than just answering you. The same trend that produced fast, cheap models that now code like the big labs is what makes a feature like this cheap enough to run on by default.
And the interaction model is familiar for a reason. Autocomplete, predictive text, and smart replies trained all of us to accept a good-enough guess with one tap. Extending that from words to full prompts is the natural next step. Expect to see “here’s your likely next move, Tab to accept” spread well beyond Codex into general chat assistants and other agent tools over the next year.
The skill that still matters
Here’s the quiet irony. The better these predictions get, the more valuable it becomes to know what a good prompt even looks like, because your job shifts from writing prompts to judging them. You can’t tell whether a suggested message is right if you’ve never developed a feel for what right looks like.
That’s a strong argument for still building your own prompting muscle, and for keeping a reusable library of the prompts that actually work for you. The prediction engine handles the generic follow-ups; your saved, sharpened prompts handle the work that’s distinctly yours. The two complement each other rather than compete.
The takeaway
Composer predictions are a small feature with a big tell. They point at a future where your tools don’t just respond, they lean forward and offer the next step, and the good ones hand it to you as a draft you’re free to rewrite. That’s exactly the right bargain: the AI does the typing, you keep the thinking.
If you’re on a plan that has it, try it for a day of real work and notice how often the guess is right, and more importantly, catch yourself before you accept the ones that aren’t. The people who get the most out of this won’t be the ones who Tab the fastest. They’ll be the ones who stay in charge of where the conversation goes, letting the prediction carry the busywork while they aim the tool at what it’s actually for. That’s the whole promise of AI that works for humans: less typing, more deciding.
Sources & further reading:
- Composer predictions in Codex – OpenAI Help Center
- Composer Predictions – ChatGPT Learn
- ChatGPT release notes – OpenAI Help Center
Related Reading
- The Everyday AI Prompts That Actually Save You Time
- Stop Accepting the First AI Answer: Simple Ways to Get a Better Response Every Time
- AI Agents in 2026: The Autonomous Assistants Transforming Your Daily Workflow